Choose FLUX 3 Image for compositions that need many references, precise placement, or 4K output. Start with Qwen Image 3.0 Pro for multilingual text and dense layouts, and test Standard when speed and cost matter. The best choice is the model that delivers usable images with fewer corrections. Compare the exact variant, resolution, and API provider before committing to a workflow.
Key Takeaways
Quality: No decisive overall winner is established by the small third-party comparison.
Control: FLUX documents up to 10 references, 4K output, and bounding-box placement; verify the selected endpoint’s limits.
Typography: Qwen Image 3.0 Pro is officially positioned for multilingual small text and complex layouts.
Qwen was faster in the cited platform test, and its native Singapore pricing is published by output tier. Compare actual cost per accepted image.
Reviewed for clarity, source attribution and current API terminology.
Speed and cost:
Access: Native APIs and CometAPI have separate availability states. Use the correct model ID and provider-specific billing rules.
What Are FLUX 3 Image and Qwen Image 3.0?
FLUX 3 Image: Overview
BFL introduced the FLUX 3 family on July 23, 2026. Its announcement describes joint learning across image, video, and audio. Family-level multimodal training does not mean that every modality is exposed by the image endpoint.
FLUX 3 Image is BFL’s image-generation and editing model for reference-guided composition and controlled scene changes. Its documented reference capacity and spatial controls make it a candidate for product composites and workflows where object placement matters. Evaluate the full model separately from Klein.
BFL offers FLUX 3 Image and a separate FLUX 3 Image Klein model. They should be evaluated and licensed separately.
Qwen Image 3.0: Overview
Qwen Image 3.0 officially emphasizes complex prompts, dense layouts, multilingual rendering, and small text. Pro may be preferable for more demanding layouts, but the official model pages do not establish that these capabilities are exclusive to Pro. Keep the variant explicit when comparing quality, speed, and billing.
Qwen’s official guide describes Standard and Pro as image generation and editing models. This comparison does not infer Qwen Image 3.0’s parameter count or architecture from older Qwen releases. A parameter-by-parameter architecture ranking is not supported by the sources used here.
FLUX 3 Image vs Qwen Image 3.0: Specifications Compared
Dimension
FLUX 3 Image
Qwen Image 3.0
Reference images
Up to 10
1–3 editing inputs (Standard and Pro)
Maximum output
4K resolution option
2048 × 2048
Composition controls
Bounding boxes and regional editing
Reference-guided instruction editing
Typography positioning
Text rendering supported; test exact copy
Pro emphasizes multilingual small text and dense layouts
Variants compared
Full FLUX 3 Image; Klein is separate
Standard and Pro; distinguish results by variant
Native API access
BFL documents a generation endpoint
Alibaba Cloud documents Standard and Pro
More references and a larger canvas give you more options, but do not guarantee a better image. Judge both models on your actual brief: accurate text, correct placement, and consistent edits.
Image Quality and Prompt Adherence
Image quality should be evaluated across photorealism, prompt adherence, text fidelity, and editing consistency. Product photography requires credible lighting and materials; information graphics require exact words and layout; iterative editing requires preservation of objects not targeted by a change.
Dimension
Evaluation
Best-fit example
Photorealism
Light, anatomy, reflection, texture
Product shots
Prompt adherence
Counts, positions, exclusion rules
Commercial brief
Typography
Spelling, punctuation, legibility
Poster, infographic
Edit consistency
Identity and unaffected-area preservation
Campaign variants
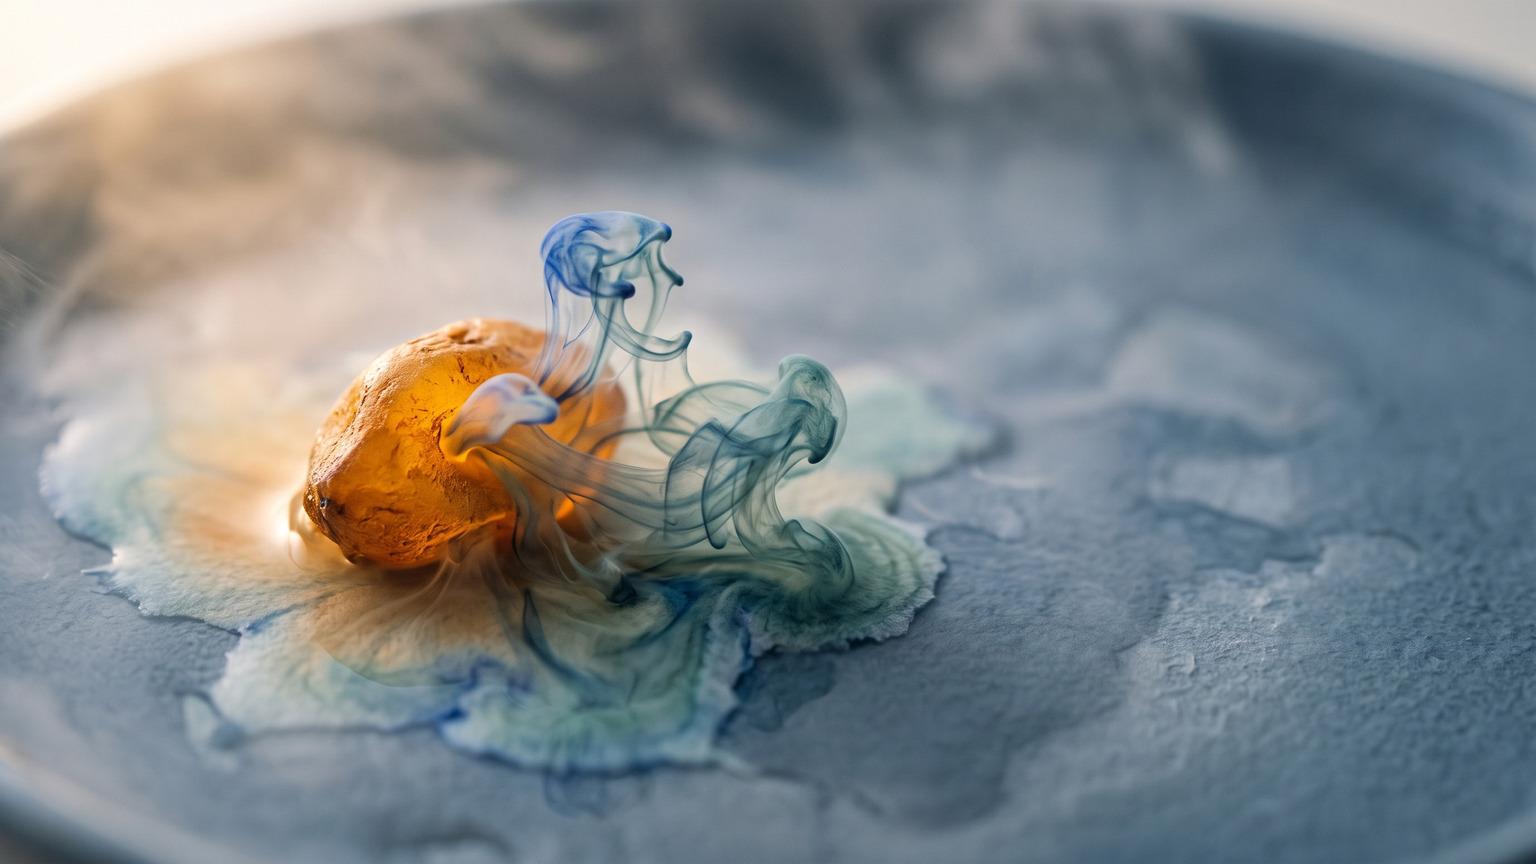
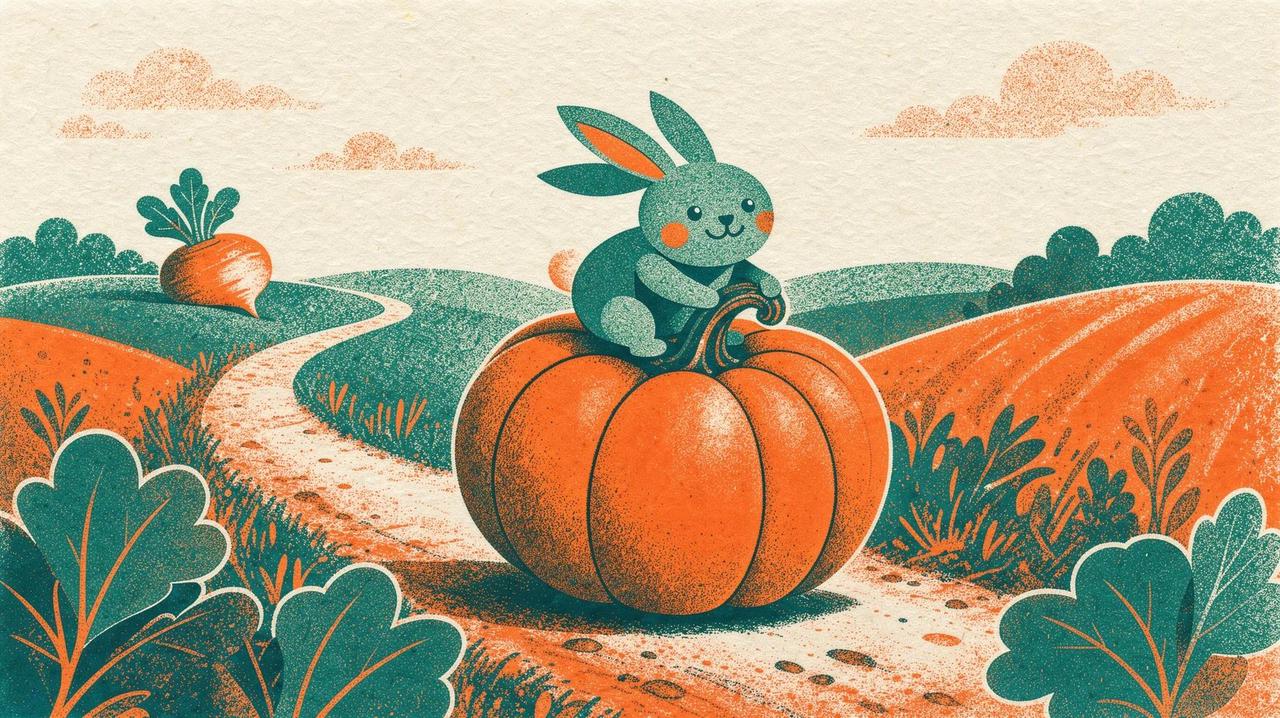
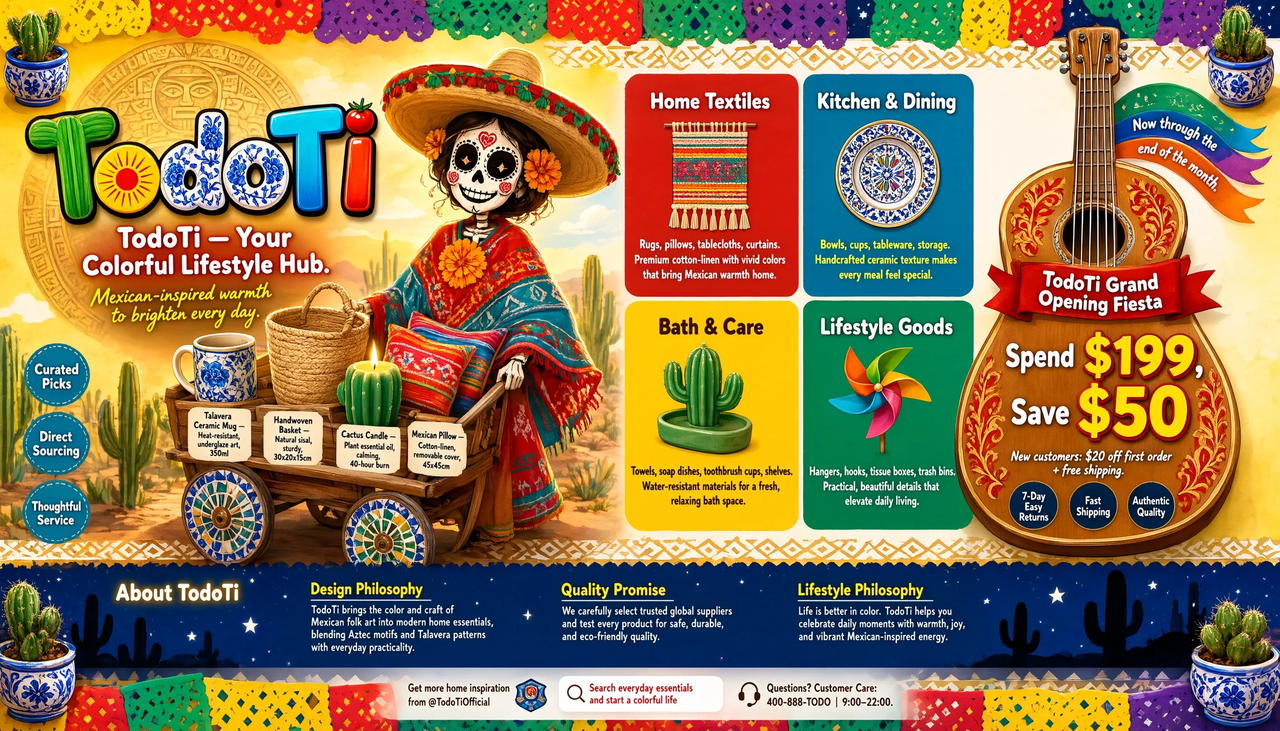
Official samples illustrate supported workflows, but they are selected demonstrations, not a matched head-to-head test. The two examples below use different prompts and should not be scored against each other.
BFL publishes this illustration in its FLUX 3 Image quickstart. It is a full-model example, rather than a Klein output.
Alibaba Cloud presents this image as a Qwen-Image complex-layout example. The gallery labels the family rather than identifying a Standard-versus-Pro result, so the image is not used to establish a variant ranking.
Text Rendering and Typography
Alibaba’s official positioning for Qwen Image 3.0 Pro emphasizes complex layouts, multilingual fonts, and small text. This supports choosing Pro as a first test for menus, posters, and infographics, but it is not a controlled proof that Pro outperforms FLUX on every text prompt.
A single spelling error can make an otherwise attractive marketing image unusable. Qwen Pro is therefore a natural first model for Chinese posters, dense infographics, and interface mockups, although every production-critical label still requires human or automated verification.
Evaluate exact strings, punctuation, line breaks, font legibility, and the smallest production text size. Use the same copy and layout requirements for both models, and score incorrect characters separately from visual appeal. For bilingual assets, review each language rather than relying on an attractive headline.
Reference Images, Resolution, and Editing
BFL documents two to ten reference images for multi-reference composition. Its full-model workflow exposes a 4K resolution option. The Klein announcement separately describes bounding boxes for placement or confined edits as a shared capability with the full model.
Qwen’s editing workflow accepts up to three input images. Both Standard and Pro support generation and editing; select the exact model ID rather than transferring a result from one variant to the other. More references or a larger output canvas are specification advantages, not automatic guarantees of better identity consistency.
For local edits, check both the requested change and preservation of everything outside the target region. For product composites, evaluate object identity, relative scale, occlusion, lighting consistency, and exact placement. Compare final delivered dimensions and aspect ratio before treating a 4K-versus-2K result as a quality contest.
FLUX 3 Image vs Qwen Image 3.0: Benchmark Results
The figures below are the earlier BudgetPixel snapshot cited in this comparison, not a new test. The source page could not be retrieved for the October 23 update, so treat these numbers as historical context and check the live comparison before using them to choose a model.
Reported metric
FLUX 3 Image
Qwen Image 3.0
Preference share
43%
39%
Median generation time
24.4 seconds
7.2 seconds
Shared prompt set
102 prompts
102 prompts
Test setting
BudgetPixel; default settings; 1:1 images
BudgetPixel; default settings; 1:1 images
The BudgetPixel AI Image Arena comparison reports 102 identical prompts, default settings, a 1:1 image format, and blind community voting. The 102-prompt count and the 74-vote count use different denominators. The preference percentages are calculated from the 74 head-to-head votes, not from all 102 prompts. The prompt count and vote count measure different things.
Test Conditions and Evaluation Limits
These are third-party platform observations, not official vendor benchmarks or results measured for this article. The overview does not establish exact pixel dimensions, execution region, hardware, model snapshot, concurrency, or a full latency-timing protocol. Those limits prevent attributing the entire latency gap to the underlying model.
The small preference sample supports no decisive overall quality winner; it does not demonstrate that the models are equivalent. Check the live snapshot date when reusing the figures.
The cited results compare the platform’s FLUX 3 Image and Qwen Image 3.0 entries. They do not establish a separate Qwen Pro score. Do not transfer the reported speed or preference share to Pro, to another gateway, or to a different resolution without testing that configuration.
FLUX 3 Image vs Qwen Image 3.0: Pricing, Speed and API Access
A faster generation is valuable only when the image meets your brief. Compare total time to approval, including edits and retries, alongside cost per accepted image. For batch work, also measure throughput at your allowed concurrency.
Native Pricing and Cost Example
The table uses USD prices for Alibaba Cloud’s Singapore international deployment, checked on October 23, 2026. Official rates vary by region: select your deployment before estimating costs. CometAPI has its own billing. BFL’s public page lists resolution tiers, but no readable numeric FLUX 3 Image rate was available in this check; use the request cost or your account quote.
Billing item
FLUX 3 Image: native pricing
Qwen Standard: Singapore
Qwen Pro: Singapore
1K output
Resolution-based; obtain the current BFL rate
$0.030 / image
$0.040 / image
2K output
Resolution-based; obtain the current BFL rate
$0.030 / image
$0.075 / image
Reference-image input
Check the native billing terms
$0.003 / image
$0.003 / image
Example: 100 successful 2K outputs, one reference per request
Use current BFL output and reference charges
$3.30
$7.80
$7.80
BFL prices the full model by resolution and includes request cost in its submission response. Check the BFL pricing page and your account before budgeting; Klein rates do not apply to the full model.
For the example above, Standard costs 100 × ($0.030 + $0.003) = $3.30; Pro costs 100 × ($0.075 + $0.003) = $7.80. This assumes one reference and one successful 2K output per request, with no discounts or retries. Include every billed attempt when calculating cost per approved image.
CometAPI Availability and Billing
The CometAPI FLUX 3 Image page shows “Coming soon” alongside an “Available” health indicator. Confirm callable access in your account before choosing this route.
The CometAPI Qwen Image 3.0 listing identifies qwen-image-3.0 as available, starting at $0.024 per request. Confirm charges for your size and input settings; this gateway rate is separate from Alibaba Cloud’s native prices. Catalog details checked October 23, 2026.
Model identity: Confirm Standard versus Pro, the callable ID, and account access.
Input and output compatibility: Check image encoding, reference limits, resolution, and asynchronous response handling.
Billing: Verify charges for each size, input reference, output count, and retry.
Reliability: Test timeouts, moderation responses, rate limits, and a known-working fallback before production use.
Compare Both Models With One Prompt
Product Poster Evaluation Example
Use a product-poster brief to test object placement, material realism, typography, and reference fidelity together. The following is an evaluation design, not a new measured model result. Use licensed product references and run the same brief separately against full FLUX 3 Image, Qwen Standard, and Qwen Pro when each route is available.
Example prompt: Create a square studio product poster using the supplied reference bottle. Preserve its shape, cap, and label artwork. Place the bottle in the right third on pale stone, with soft light from the upper left and an empty left third for copy. Add the exact headline “DAILY CLEAR” above the exact subheading “Simple care. Every day.” Do not add other words, logos, objects, or watermarks.
Start with one identical reference, a common supported output size, the same aspect ratio, and one output per request. Record any automatic prompt rewriting instead of assuming the providers preprocess the prompt identically. Hold input preprocessing and review criteria constant; document settings that cannot be matched.
Check
Acceptance criterion
What to record
Reference fidelity
Preserve bottle shape, cap, and label.
Record identity or artwork changes.
Prompt adherence
Keep the bottle right and copy space left.
Record misplaced or extra objects.
Typography
Render both strings exactly and legibly.
Record spelling and layout errors.
Visual quality
Use credible light, materials, and reflections.
Record accept/reject reasons.
Operational cost
Count all billed attempts.
Include inputs, edits, and retries.
Latency
Time submission to finished output.
Record median, tail, and errors.
Repeat across multiple real briefs and multiple outputs per configuration. Blind the reviewers to model names, keep rejected images in the record, and report the test date, sample size, endpoint, exact variant, resolution, settings, and approval rate. Test a subsequent edit with the same instruction and check changes outside the intended area separately.
FLUX 3 Image or Qwen Image 3.0: Which Should You Choose?
Workflow
First candidate to evaluate
Reason and validation
Many-reference product composite
FLUX 3 Image
Documented reference capacity; test identity and occlusion
Native 4K creative output
FLUX 3 Image
Documented 4K option; check actual dimensions and cost
Multilingual menu or dense infographic
Qwen Image 3.0 Pro
Official layout emphasis; verify every required string
Frequent social-asset iteration
Qwen Image 3.0 Standard
Evaluate throughput and accepted-output cost on your provider
Packaging or premium product imagery
Both, using matched briefs
Typography, materials, and brand consistency all matter
Choose FLUX for Composition Control
Start with FLUX when the brief needs many references, explicit object placement, constrained local edits, or native 4K output. These documented capabilities justify a pilot; they do not establish better photography or lower total production cost. Verify identity preservation, output dimensions, and current billing on the intended route.
Choose Qwen for Text and Layouts
Start with Qwen Pro for dense information design and multilingual visual text. Evaluate Standard for recurring graphics where throughput and accepted-output cost matter. Review critical copy character by character, and test both variants when extra layout accuracy could offset Pro’s higher output price.
Use Both When Briefs Have Different Requirements
A team can evaluate FLUX for complex composites and Qwen Pro for localized text-heavy assets. Treat this as task routing, rather than assuming that passing an image through both models improves it. If a fallback is used, trigger it on a concrete failed check and include its cost, latency, and risk of visual drift in the result.
Validate Before Switching
A robust evaluation uses identical prompts, multiple runs per prompt, blind review, and a record of accept/reject decisions. Track typography accuracy, task-specific adherence, median and tail latency, retry counts, and cost per approved image—not just visually impressive samples.
Include difficult cases from real briefs, not only attractive showcase prompts. Keep a separate scorecard for each variant, freeze the provider settings during a test, and record time to first result as well as time to an approved asset. These measurements determine whether a documented feature helps the actual workflow.
Include the current production model as a baseline.
Set minimum acceptance rates for exact text, identity, placement, and edit preservation before testing.
Compare total cost per accepted asset and end-to-end approval time at the intended resolution and load.
Keep the existing route when a candidate’s retries, failures, or maintenance costs erase its apparent advantage.
Conclusion
Start with FLUX 3 Image when the workflow depends on multiple references, explicit spatial placement, bounding-box editing, or native 4K output. Start with Qwen Image 3.0 when the workflow depends on long, information-dense prompts, multilingual text, small typography, or frequent iteration. Test Standard and Pro separately because their prices, rate limits, and endpoint behavior differ. The available third-party comparison is too limited to establish a universal image-quality ranking, so the final decision should be based on approval rate, end-to-end workflow time, reliability, and cost per approved asset.
Choose the model that produces more approved assets within your cost and latency budget. Keep native pricing separate from gateway billing, distinguish Standard from Pro and the full FLUX model from Klein, and confirm access before committing to an integration.
FAQ
How can a team keep a FLUX 3 Image vs Qwen Image 3.0 evaluation repeatable?
Freeze a representative prompt set, output dimensions, provider, model ID, and preprocessing rules. Record every output, including rejections, and ask reviewers to score outputs without seeing model names. Preserve the settings and dates with the results; if a provider changes a model or its defaults, rerun the affected cases before comparing the new scores with the old ones.
How should teams validate private reference images before using either API?
Check the selected provider’s retention, training-use, deletion, and data-location terms before uploading confidential assets. Native service terms and gateway terms may differ, so evaluate the actual route the images will take. Use approved or de-identified samples for an initial trial when the production assets are not yet cleared for that route.
How can developers prevent duplicate charges during image-generation retries?
Record the request identifier and task state before deciding to submit again. A client timeout does not prove that generation failed: first check whether the original job can still complete. Use an idempotency mechanism only if the selected provider documents one, and distinguish polling an existing task from creating another billable generation.
What should a FLUX 3 Image or Qwen Image 3.0 regression set include?
Include fixed examples with exact text, object counts, brand colors, identity references, and edits that must preserve surrounding content. Retest them after a model, prompt template, or provider update. Keep accepted baseline outputs and rejection reasons so that a visually appealing update cannot hide a decline in a production-critical requirement.