
TL;DR
The OpenAI Decisions API is a specialized endpoint that turns text and images into actionable, machine-readable decisions rather than generated prose. It uses GPT-6 Luna and supports predicate, choice, and score questions. OpenAI reports approximately 10× faster performance than its Responses API for supported decision tasks and standard input pricing of $0.10 per million tokens.
Key Takeaways
- Purpose-built decisions: predefined questions rather than free-form conversation.
- Three decision types: predicate, choice, and score.
- Probability-aware automation: route ambiguous or consequential inputs to human review.
- Vendor-reported speed gains and input-only standard pricing of $0.10 per million tokens make the endpoint relevant to high-volume decisions.
- Best for routing, classification, visual checks, and AI-agent decision gates.
What Is the OpenAI Decisions API?
The OpenAI Decisions API evaluates information and returns bounded, machine-readable decisions. OpenAI released it in beta on October 6, 2026. This guide is for developers who already understand API keys and JSON and want to evaluate classification or routing workflows. Product details were checked on October 12, 2026.
The POST /v1/decisions request schema accepts a model, shared text or image input, and developer-defined questions. The dedicated endpoint returns typed judgments rather than explanatory prose.
OpenAI Decisions API specifications
| Specification | Documented endpoint details |
|---|---|
| Product type | Specialized API endpoint, not a standalone foundation model |
| Endpoint | POST /v1/decisions |
| Underlying model | gpt-6-luna |
| Inputs | Text and images |
| Decision types | predicate, choice, score |
| Outputs | Typed decisions and probability information |
| Performance | Approximately 10× faster than Responses API (vendor claim) |
| Standard input price | $0.10 / 1M tokens |
| Output charge | None for Decisions API |
| Tool calling / streaming | Not supported directly by this endpoint |
Current availability and access
As of October 15, 2026, the official guide lists public beta access, with gpt-6-luna as the only supported model. Send requests to POST /v1/decisions; beta status is not a guarantee of production stability.
Use an OpenAI API project and check its model access, billing status, and rate limits before deployment. The guide lists Python SDK 3.26.0 or later; account-specific access should be confirmed with a small test request.
Eligible customers can use Zero Data Retention and HIPAA arrangements. The guide lists US and European regional processing; eligibility and contractual requirements still apply. Access through a third-party Luna interface does not establish compatibility with this dedicated endpoint.
How Does the OpenAI Decisions API Work?
A request combines shared input evidence with developer-defined questions. The API evaluates the input using GPT-6 Luna and returns answers that application code can use to automate, review, or escalate. Multiple questions may share the same input, although dependent questions should be sequenced by the application.
Predicate evaluation
A predicate evaluates whether a specified condition holds. A retailer could ask whether a photograph shows visible product damage; the response provides a probability between 0 and 1.
Illustrative predicate answer excerpt.
{
  "type": "predicate",
  "name": "visible_damage",
  "probability": 0.92
}
Choice selection
A choice question selects among explicitly supplied categories, such as Billing, Technical Support, or Account Access. Distribution and confidence fields support downstream routing and escalation policies.
Score evaluation
A score question evaluates input against an ordered rubric. The expected score can reflect the probability-weighted indices of the defined levels; this does not automatically represent a calibrated real-world risk.
| Index | Severity | Interpretation |
|---|---|---|
| 0 | Low | No immediate action |
| 1 | Moderate | Routine follow-up |
| 2 | High | Significant customer impact |
| 3 | Critical | Immediate escalation |
What Are the Main Features of the OpenAI Decisions API?
Fast, bounded execution
Typed outputs remove much of the need to generate prose, parse text, or retry malformed answers. OpenAI describes approximately tenfold relative speed improvement on supported decision tasks; actual gains will depend on input length, network overhead, and concurrency.
Multiple questions over shared context
One support ticket can be evaluated for department, urgency, and review eligibility in one request. Applications still need to enforce deterministic business rules and authorization checks.
Text and image understanding
Text and images support ticket routing, screenshot triage, and visual inspection. Consult the official documentation for supported image formats, size limits, and currently accepted payload structures.
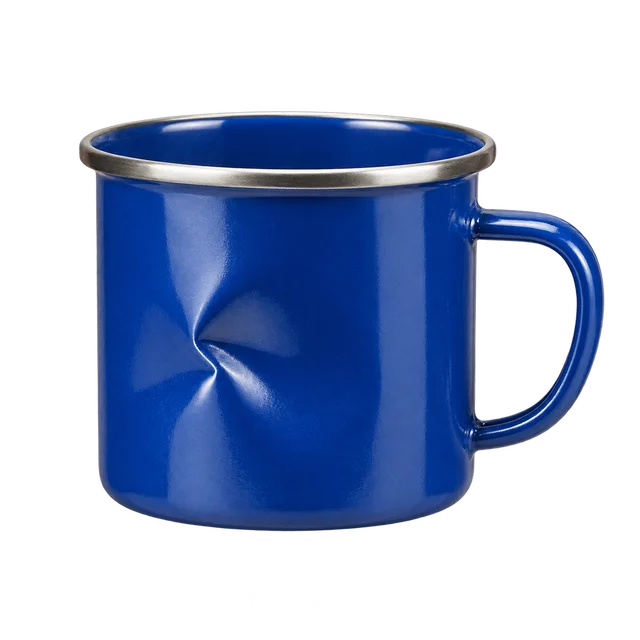
OpenAI uses this dented mug in its visual decision example. The image illustrates observable damage; it is not evidence of a measured accuracy rate. This endpoint accepts inline base64 image data URLs, not hosted image URLs or file IDs.
Probability-aware automation
Reported confidence is not guaranteed accuracy. Teams should tune thresholds against labeled holdout data, using separate thresholds for cases with high false-positive or false-negative consequences.
Security and data controls
Data retention, regional processing, and regulated use depend on the account configuration and applicable contractual requirements. Confirm eligibility before processing regulated or sensitive information.
How Much Does the OpenAI Decisions API Cost?
The reported standard rate is $0.10 per million input tokens with no output-token billing through the dedicated Decisions endpoint. Regional processing or long-context multipliers can alter the final bill.
| Component | Dedicated endpoint pricing |
|---|---|
| Standard input | $0.10 per 1M tokens |
| Output tokens | $0 |
| Cache reads / writes | $0 |
| Regional processing | Premium may apply |
| Long context | Multiplier may apply |
| Billing unit | Input tokens |
How much can Decisions API save versus Responses API?
Compare equivalent tasks on the same model. The Decisions guide lists $0.10 per million input tokens and no output or cache charges. The Luna model page lists Standard text pricing of $0.10/M uncached input and $0.50/M output for general model use.
Illustrative calculation, not a benchmark: 1,000,000 text requests, 500 uncached billable input tokens per request on each endpoint, one classification per request, and no regional or long-context premiums. For Responses, use total billed output tokens, including any billed reasoning tokens, rather than visible answer length alone.
At these assumptions: Decisions cost = N × I × $0.10 / 1,000,000. Responses cost = N × (I × $0.10 + O × $0.50) / 1,000,000. Savings percentage = (Responses cost − Decisions cost) / Responses cost × 100%, where N is requests, I input tokens/request, and O billed output tokens/request.
| Billed Responses output / request | Decisions cost / 1M requests | Responses cost / 1M requests | Estimated savings |
|---|---|---|---|
| 5 tokens | $50.00 | $52.50 | $2.50 (4.8%) |
| 20 tokens | $50.00 | $60.00 | $10.00 (16.7%) |
| 100 tokens | $50.00 | $100.00 | $50.00 (50.0%) |
The savings above come from the assumed Responses output bill; they are not a fixed endpoint discount. Recalculate with measured input usage, cache hits, cache writes, processing tier, and retries. Cached input or Batch/Flex rates can change the result. Add tool fees, human review, and infrastructure separately. Compare cost per accepted correct decision after checking quality and latency; a short label and a longer explanation are different workloads.
OpenAI Decisions API vs Responses API vs Jev and Aplomb 1
The table focuses on dedicated decision services. For generated explanations, custom extraction schemas, or tool workflows, use the Responses API as described in the OpenAI decision guide. A decision can select a workflow branch, while Responses generates content or requests a tool call, with application code handling custom tool execution.
Capabilities and pricing overview
| Dimension | OpenAI Decisions API | Jev 1.13 | Aplomb 1 |
|---|---|---|---|
| Inputs | Text and images | Text; experimental images with opt-in | Text, JSON, images, video and audio |
| Standard input price / 1M tokens | $0.10 | $0.042 | $0.02 |
| Access | Hosted OpenAI API | Hosted TypeSafe API | Hosted API; downloadable weights under the EmpirioLabs Model License |
| Evaluation fit | Routing, filtering and scoring in OpenAI workflows | Classification and intent routing | Mixed-media decisions; deployment requiring weights |
Selection scope: Jev and Aplomb are included for their published decision capabilities, not as a popularity ranking. Specifications and standard input prices were checked on October 16, 2026. TypeSafe still maps jev-latest to 1.13 and jev-preview to 1.14, so this comparison pins 1.13. Jev image support is experimental. Aplomb weights are license-restricted; check the terms for commercial deployment. Published token prices are not a quality ranking or an estimate of total workflow cost.
Workflow selection
Shortlist services by required inputs and deployment options, then test them on the same labeled cases. Match input preparation, decision rubrics, end-to-end latency measurements, and human-review policies. Compare routing accuracy, missed cases, review workload, and cost per accepted correct decision. Report these together so a lower token price or faster answer does not conceal additional errors or review costs.
How Can You Use the OpenAI Decisions API?
Step 1: Configure credentials
Create an API key and supply it as the OPENAI_API_KEY environment variable. Never hard-code secret keys in repositories or front-end applications.
Step 2: Send a request with cURL
The following request follows the official choice example schema. Set OPENAI_API_KEY before running it; a successful response contains an answers array. The shell commands use Bash syntax.
Route a support request with cURL.
curl https://api.openai.com/v1/decisions \
  -H "Authorization: Bearer $OPENAI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gpt-6-luna",
    "input": "I was charged twice for my order.",
    "questions": [
      {
        "type": "choice",
        "name": "department",
        "instructions": "Which department should handle this complaint?",
        "choices": [
          {"value": "billing", "description": "Payments and refunds"},
          {"value": "technical", "description": "Product issues"},
          {"value": "other", "description": "Everything else"}
        ]
      }
    ]
  }'
Step 3: Integrate with Python
Install the required Python SDK.
pip install --upgrade "openai>=3.26.0"
Request and inspect a choice decision.
from openai import OpenAI

client = OpenAI()
result = client.decisions.create(
    model="gpt-6-luna",
    input="I was charged twice for my order.",
    questions=[{
        "type": "choice",
        "name": "department",
        "instructions": "Which team should handle this request?",
        "choices": [
            {"value": "billing", "description": "Payments and refunds"},
            {"value": "technical", "description": "Product issues"},
            {"value": "other", "description": "Other requests"}
        ]
    }]
)
answer = result.answers[0]
if answer.type == "refusal":
    print("Decision refused")
elif answer.type == "choice":
    print(answer.choice, answer.confidence)
Step 4: Define an escalation rule
Apply an illustrative routing threshold.
if answer.type == "choice":
    if answer.choice != "other" and answer.confidence >= 0.90:
        print("Eligible for automatic routing")
    else:
        print("Send to human review")
The 0.90 threshold is illustrative, not a provider guarantee or officially recommended default. Validate it against real examples and business risk.
How Can You Access GPT-6 Luna Through CometAPI?
Developers can use the GPT-6 Luna API in CometAPI for general-purpose model tasks. This should not be confused with support for the dedicated OpenAI Decisions endpoint, which requires separate compatibility verification.
Classify text through CometAPI Responses.
import os
from openai import OpenAI

client = OpenAI(
    api_key=os.environ["COMETAPI_KEY"],
    base_url="https://api.cometapi.com/v1"
)
response = client.responses.create(
    model="gpt-6-luna",
    input=(
        "Classify as billing, technical, or other. "
        "Return only the category. "
        "Request: I was charged twice for my order."
    )
)
print(response.output_text)
This sample is general-purpose classification through the CometAPI-compatible model interface; it does not return the native Decisions API probability structure or inherit its input-only price.
What Are the Best Use Cases for the OpenAI Decisions API?
These are illustrative application workflows, not reported deployments or benchmark results. They use the predicate, choice, and score question types in the official Decisions guide. Application code performs the downstream actions.
Customer support classification
Provide the ticket text, relevant conversation history, and a predefined list of support teams. A choice question can select Billing, Technical Support, or Account Access; a separate score question can assess urgency against a written rubric. Application code can assign the suggested queue and send uncertain or incomplete cases to a reviewer.
Evaluate the workflow on tickets labeled by support staff, measuring routing accuracy by category, missed urgent cases, reassignment rates, and review workload. Compare these results with the existing routing process before expanding deployment.
Content moderation and review queues
Supply submitted text or images together with clearly defined review categories. Predicate questions can evaluate whether particular conditions appear in the content, while a score question can prioritize review according to a documented severity rubric. The application can then place flagged items in the appropriate queue and present the relevant content to reviewers; the endpoint itself does not remove content or enforce platform rules.
Evaluate missed violations, unnecessary flags, reviewer agreement, and queue delays on representative labeled examples. Adjust thresholds separately for categories with different consequences.
E-commerce image inspection
Provide product photographs and the inspection criteria relevant to the item, such as visible cracks, tears, or damaged packaging. Predicate questions can assess whether each condition appears, and a score question can apply a defined severity rubric when the images contain sufficient evidence. Application code can request another photograph or create a human inspection task when evidence is unclear.
Evaluate detection accuracy against inspected items, including missed damage and false alarms across product categories and image conditions. Keep refund or replacement decisions in the retailer’s existing approval workflow.
AI-agent action gating
Provide the proposed action, its arguments, the relevant user request, and the application’s written execution rules. Predicate questions can assess whether the proposal matches the requested task or requires review. Application code can use the result to select a predefined branch: continue, request clarification, or escalate. Independent permission checks must still determine whether execution is authorized; the model’s judgment is only one input.
Evaluate the gate with labeled action proposals, measuring missed unauthorized actions, unnecessary escalations, and sensitivity to incomplete or conflicting context before connecting it to execution.
Document and email triage
Provide the document or email text, relevant metadata, and a fixed set of categories such as invoice, support request, meeting request, or other. A choice question can select the category, while predicate questions can identify conditions such as missing required information. Application code can send the item to the appropriate extraction, retrieval, or review workflow without asking the decision endpoint to perform those later steps.
Evaluate category accuracy, incorrect downstream routing, review volume, and processing time using representative labeled records, including ambiguous items and unfamiliar formats.
What Are the OpenAI Decisions API’s Limitations?
The API does not generate arbitrary explanatory content, execute tools directly, or eliminate the need to test predictions. Missing categories and poorly written decision rubrics can produce inappropriate outcomes. Confidence values may be miscalibrated; high-stakes automation still needs safeguards, human review, and authorization logic.
Conclusion
The Decisions API is promising for high-volume bounded judgments because it combines typed probability outputs with a simplified token-pricing model. Teams should compare it with Structured Outputs and alternative decision models using the same labeled cases, latency measurements, and full workflow costs. The core opportunity is identifying steps in an AI application that need a choice rather than generated prose.
FAQs
How should OpenAI Decisions API refusals be handled?
Treat a refusal as a separate workflow outcome. Check answer.type before reading choice, score, or probability fields. Log the question name and route the request to a review or recovery path; never interpret a refusal as a negative predicate or a zero score.
How can Decisions API thresholds be maintained over time?
Choose thresholds on labeled holdout examples, then monitor accuracy among accepted decisions and the share sent for review. Re-evaluate after changing categories, instructions, input sources, or model behavior. Keep a versioned rubric so changes in routing can be traced to the configuration that produced them.
How should OpenAI Decisions API latency tests be reported?
Record the date, region, model identifier, question count, text length, image size, concurrency, client version, retry policy, and comparison endpoint configuration. Report end-to-end p50 and p95 with sample counts and quality results, so a speed gain is not achieved merely by accepting more errors.
How should Decisions API categories evolve without breaking integrations?
Use stable machine-readable values and maintain an explicit mapping to downstream queues. Add a fallback category and test historical edge cases before deploying new descriptions. If a category is renamed, update the routing map and rubric together instead of allowing unknown values to reach production actions.
What should be logged for a Decisions API routing audit?
Record the rubric version, selected category, relevant probabilities or confidence, threshold, model identifier, timestamp, and action taken. Limit stored input content to what the workflow requires and apply the organization’s retention policy. An audit record should show why application logic routed or escalated the case.