
TL;DR
GPT-Image-2.5 does not have a single fixed “price per image.” OpenAI charges API usage by tokens. Both GPT-Image-2.5 Flare and GPT-Image-2.5 Sunburst use the same official token rates: $5 per million text-input tokens, $8 per million image-input tokens, and $30 per million image-output tokens. Cached text and image inputs cost $1.25 and $2 per million tokens respectively.
For a 1024×1024 image, third-party calculator observations suggest output-only generation can range from roughly $0.006 at low quality to about $0.211 at max quality. High quality is around $0.053 in that planning model. Actual bills depend on prompt tokens, reference images, retries, editing inputs, and real output-token usage.
Key Takeaways
- OpenAI charges the GPT-Image-2.5 API by tokens rather than a universal fixed price per image.
- Flare and Sunburst have the same token rates; Sunburst is not a more expensive model per token.
- Official rates are $5/M text input, $8/M image input, and $30/M image output.
- GPT-Image-2.5 introduces low, medium, high, xhigh, max, and auto quality modes.
- A planning estimate for a 1024×1024 image is approximately $0.0059 at low, $0.0527 at high, and $0.2107 at max, before input-token costs.
- Flare is the better default for high-volume and latency-sensitive generation, while Sunburst targets precision editing and premium creative workflows.
- CometAPI advertises a 20% discount on its GPT-Image-2.5 model APIs, with headline pricing of $4/M input and $24/M output against the corresponding $5/M and $30/M headline official rates.
What Is GPT-Image-2.5 and What Are You Paying For?
OpenAI released ChatGPT Images 2.5 on September 8, 2026. The update focuses on sharper detail, more natural lighting and textures, stronger preservation of reference subjects, more reliable multi-turn editing, and lower generation latency. OpenAI says generation latency can be up to 50% lower than Images 2.0.
The API family has two variants. GPT-Image-2.5 Flare is optimized for fast, high-quality everyday generation and is OpenAI’s recommended default for most applications. GPT-Image-2.5 Sunburst emphasizes editing precision and premium creative workflows where preserving an existing subject or composition is more important than minimum latency.
| Specification | GPT-Image-2.5 Flare | GPT-Image-2.5 Sunburst |
|---|---|---|
| API model ID | gpt-image-2.5-flare | gpt-image-2.5-sunburst |
| Positioning | Fast everyday generation | Precision generation and editing |
| Input | Text and images | Text and images |
| Output | Images | Images |
| Image generation | Yes | Yes |
| Image editing | Yes | Yes |
| Quality settings | low, medium, high, xhigh, max, auto | low, medium, high, xhigh, max, auto |
| Recommended square size | 1024×1024 | 1024×1024 |
| Recommended landscape size | 1536×1024 | 1536×1024 |
| Recommended portrait size | 1024×1536 | 1024×1536 |
| Transparent output | PNG / WebP | PNG / WebP |
| Best fit | High-volume generation, rapid iteration | Product imagery, campaign creative, precise edits |
| Official image-output rate | $30/M tokens | $30/M tokens |
The core model documentation confirms that both variants accept text and image input and produce image output, while function calling, structured outputs, and fine-tuning are not part of the image-model interface.
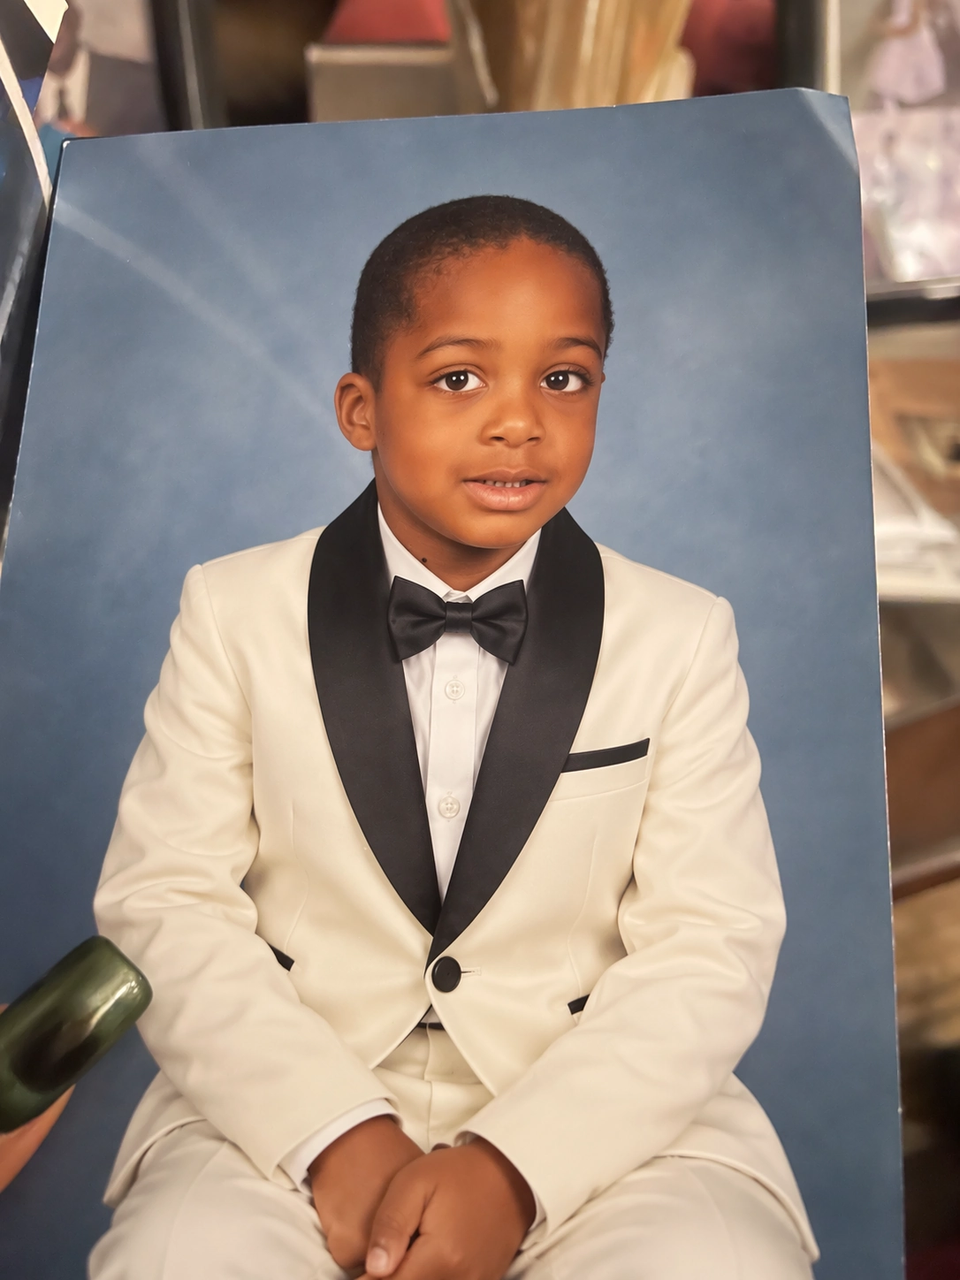
Official GPT-Image-2.5 precision-editing example published by OpenAI; the edited portrait preserves the pose and background while changing the child’s clothing.
GPT-Image-2.5 Flare is available as
gpt-image-2.5-flare, while its dated snapshot is
gpt-image-2.5-flare-2026-09-08. Sunburst similarly provides
gpt-image-2.5-sunburstand
gpt-image-2.5-sunburst-2026-09-08. Developers who require more predictable model behavior across deployments should consider whether pinning a dated snapshot is appropriate for their workflow.
How Much Does the GPT-Image-2.5 API Cost?
The simplest way to understand GPT-Image-2.5 pricing is to separate input cost from generated-image cost.
OpenAI’s official model documentation gives the following token rates for both Flare and Sunburst.
| Token type | Standard price per 1M tokens | Cached price per 1M tokens |
|---|---|---|
| Text input | $5.00 | $1.25 |
| Image input | $8.00 | $2.00 |
| Image output | $30.00 | — |
| Text output | Not billed | — |
The important number for most text-to-image workloads is $30 per million image-output tokens. A short text prompt normally contributes relatively little compared with the generated image itself. Editing workflows can cost more because reference images also consume image-input tokens.
Total API cost = text-input cost + image-input cost + image-output cost.
For a simple text-to-image call with no reference image, the image-output component will usually dominate. For an image-editing workflow with several high-resolution reference assets, input cost becomes more relevant.
How Much Does One GPT-Image-2.5 Image Cost?
This is where pricing becomes less straightforward.
Flare documentation and Sunburst documentation both state that the GPT Image 2 calculator does not estimate GPT Image 2.5 token consumption. Separately, APIdog recorded a shared GPT Image 2.5 calculator entry on September 9, 2026 with estimated output-token budgets for Flare and Sunburst. These figures are budgeting estimates rather than guaranteed official per-image prices.
| Quality | 1024×1024 output tokens | Estimated output cost | 1536×1024 output tokens | Estimated output cost |
|---|---|---|---|---|
| low | 196 | $0.00588 | 158 | $0.00474 |
| medium | 439 | $0.01317 | 343 | $0.01029 |
| high | 1,756 | $0.05268 | 1,372 | $0.04116 |
| xhigh | 3,122 | $0.09366 | 2,459 | $0.07377 |
| max | 7,024 | $0.21072 | 5,488 | $0.16464 |
These numbers cover image output only. Your real request can also include text-input tokens, image-input tokens, retries, variations, editing passes, or other usage.
A more accurate statement than “GPT-Image-2.5 costs $0.053 per image” is: a 1024×1024 high-quality generation can be budgeted at roughly $0.053 in output-token cost under the observed token estimate, before input and retry costs.
Is GPT-Image-2.5 High Quality Four Times Cheaper Than GPT Image 2 High?
At first glance, yes: the labels suggest a dramatic reduction.
APIdog’s recorded token budgets show GPT-Image-2.5 high at around 1,756 output tokens, or approximately $0.05268 for a 1024×1024 image. GPT Image 2 high was around $0.211 for the same square size.
However, this is not an apples-to-apples “same quality for one quarter of the price” comparison. The quality ladder changed.
| GPT-Image-2.5 setting | Approx. 1024×1024 output cost | Rough GPT Image 2 token-budget equivalent |
|---|---|---|
| low | $0.00588 | old low |
| medium | $0.01317 | below old medium |
| high | $0.05268 | old medium |
| xhigh | $0.09366 | between old medium and high |
| max | $0.21072 | old high |
Developers migrating an existing pipeline should not simply reuse the high quality setting and conclude that the new model is four times cheaper. If the goal is approximately the same output-token budget as the previous GPT Image 2 high setting, the closer GPT-Image-2.5 setting is max, not high.
Does GPT-Image-2.5 Sunburst Cost More Than Flare?
No—not per token. Both variants use the same official price card. Sunburst does not carry a higher $/token rate simply because it is positioned as the higher-precision model.
| Cost factor | Flare | Sunburst |
|---|---|---|
| Text input | $5/M | $5/M |
| Cached text input | $1.25/M | $1.25/M |
| Image input | $8/M | $8/M |
| Cached image input | $2/M | $2/M |
| Image output | $30/M | $30/M |
| Primary trade-off | Lower latency | More editing precision |
The difference is mainly time and workflow fit, not token price. OpenAI positions Flare as the default for most applications and says it delivers higher-quality images than GPT Image 2 at up to 50% lower latency. Sunburst is intended for more controlled editing and production-grade visual work, and can take longer to generate.
If Sunburst produces a usable campaign asset in one attempt while Flare takes two or three retries, Sunburst may actually have the lower cost per accepted image, despite having the same nominal token price.
How Good Is GPT-Image-2.5 for Its Price?
Price matters only if the output quality is competitive.
The current Arena human-preference leaderboard places both GPT-Image-2.5 variants ahead of GPT Image 2 in text-to-image generation and single-image editing. These are third-party preference scores rather than OpenAI-controlled quality benchmarks, and the GPT-Image-2.5 results are marked preliminary.
| Model | Text-to-Image Arena score | Single-Image Edit score |
|---|---|---|
| GPT-Image-2.5 Sunburst | 1421 ± 13 | 1520 ± 9 |
| GPT-Image-2.5 Flare | 1399 ± 13 | 1491 ± 9 |
| GPT Image 2 (medium) | 1381 ± 4 | 1461 ± 3 |
| Grok Imagine Image 2.0 (low) | 1315 ± 12 | 1439 ± 8 |
The benchmark set also includes the Grok Imagine Image 2.0 API in CometAPI.
The most notable result is the editing score. Sunburst leads Flare by roughly 29 points on the single-image-edit leaderboard, while both remain ahead of GPT Image 2. That aligns with OpenAI’s positioning of Sunburst as the precision-oriented option. View the image-edit leaderboard.
OpenAI’s own evaluation material is focused more heavily on safety than aesthetic preference. In its system card, the company reports final unsafe-generation-presented rates of 1.09% for Sunburst, 1.41% for Flare, and 1.64% for the Images 2.0 baseline on its adversarial safety evaluation set. These are safety measurements, not image-quality scores.
What Does GPT-Image-2.5 Cost in CometAPI?
For developers who want the model through a multi-model API gateway, both variants are available through CometAPI. The GPT-Image-2.5 Flare API in CometAPI shows $4 per million input tokens and $24 per million output tokens, compared with the corresponding $5/M and $30/M official headline figures, representing a 20% discount. The GPT-Image-2.5 Sunburst API in CometAPI publishes the same headline comparison.
| Pricing route | Input headline | Image-output headline | Discount shown |
|---|---|---|---|
| OpenAI official | $5/M text input | $30/M image output | — |
| CometAPI | $4/M input | $24/M output | 20% |
Pricing detail to verify before production budgeting: OpenAI distinguishes text input at $5/M from image input at $8/M, while CometAPI summarizes pricing with a general input/output pair. Reference-image-heavy workflows should confirm the live billing dashboard before assuming every image-input token receives the displayed input rate.
| Quality | Approx. OpenAI output cost | Approx. CometAPI output cost |
|---|---|---|
| low | $0.00588 | $0.00470 |
| medium | $0.01317 | $0.01054 |
| high | $0.05268 | $0.04214 |
| xhigh | $0.09366 | $0.07493 |
| max | $0.21072 | $0.16858 |
Again, these are estimated output costs, not all-inclusive request prices.
How Much Would 10,000 GPT-Image-2.5 Images Cost?
Large-volume pricing makes the difference easier to see. Suppose a content platform generates 10,000 square images and each output consumes approximately the observed token budget for its selected quality level.
| Quality | Approx. OpenAI output spend for 10,000 images | Approx. CometAPI output spend |
|---|---|---|
| low | $58.80 | $47.04 |
| medium | $131.70 | $105.36 |
| high | $526.80 | $421.44 |
| xhigh | $936.60 | $749.28 |
| max | $2,107.20 | $1,685.76 |
The table is useful for infrastructure budgeting, but a real production team should track something more meaningful than cost per generated image: cost per accepted image.
Using the high-quality 1024×1024 estimate from the table, ten generations cost about $0.5268 in output tokens. If six are accepted, the effective output-token cost is $0.5268 ÷ 6 = $0.0878 per accepted asset.
A more capable model that reduces retries can therefore be economically better even if a single request consumes slightly more tokens.
Which GPT-Image-2.5 Quality Setting Gives the Best Value?
For most production applications, high is a sensible starting point rather than max. Low is best suited to previews and cheap experimentation. Medium works well when generating many concepts that will be filtered later. High provides a stronger production-quality balance while remaining dramatically below the maximum token budget. Xhigh becomes attractive when assets need extra polish but do not justify the full max budget. Max should generally be reserved for final assets where fidelity matters more than generation cost.
The underlying economic advantage of the six-level ladder is that you do not have to pay maximum-quality prices during every stage of a creative workflow. A practical pipeline can generate concepts at medium, select candidates, refine the survivors at high, and make only the final hero assets at xhigh or max.
How Can You Calculate GPT-Image-2.5 Cost From API Usage?
The safest way to estimate production spend is to record actual token usage rather than rely permanently on a static per-image table. For OpenAI’s official rates, the calculation is straightforward:
Estimate each request in words: multiply text-input tokens by $5 per million, image-input tokens by $8 per million, and image-output tokens by $30 per million, then add the three amounts. For example, 120 text-input tokens plus 1,756 image-output tokens cost about $0.0006 + $0.05268 = $0.05328 before any image-input charge. For editing requests, add the image-input tokens reported by the API, especially when multiple reference images are supplied.
For a simple generation with 120 text-input tokens and 1,756 image-output tokens, the output portion is about $0.05268, while the short text prompt adds only a very small amount. For editing, add the image-input tokens returned by your real request. That is particularly important when multiple reference images are supplied.
Is GPT-Image-2.5 Worth the Price?
For most new OpenAI image integrations, Flare is the obvious starting point. It shares the same token rate as GPT Image 2, while OpenAI reports higher image quality and up to 50% lower latency. The expanded quality ladder also lets developers spend less on drafts without giving up the option of a much larger token budget for final images.
Sunburst makes more sense when failed edits are expensive. Ecommerce photography, brand campaigns, repeated image revisions, subject-preservation workflows, and other production creative can justify longer generation time because the real objective is not minimum request cost—it is minimum cost per approved asset.
For price-sensitive high-volume workloads, the strongest strategy is therefore not “always use the cheapest quality.” It is to route tasks intelligently: Flare for generation and exploration, Sunburst where edit precision materially reduces rework, and higher quality levels only after an asset has earned the extra token budget.
FAQ
Does a ChatGPT subscription include GPT-Image-2.5 API credits?
No. ChatGPT access and developer API billing are separate. API usage is charged to the API account according to the tokens processed.
What usage data should a team retain for cost audits?
Store the model, quality setting, image dimensions, text-input tokens, image-input tokens, image-output tokens, retry count, and whether the result was accepted. These fields make it possible to reconcile invoices and calculate cost per accepted asset.
How should teams estimate production cost before scaling?
Run a representative batch at the intended quality and dimensions, record the actual token usage, and divide the total batch cost by the number of accepted assets. This captures retries and rejection rates that a static per-image estimate cannot measure.